
WTB Market
SaaS platform for resellers
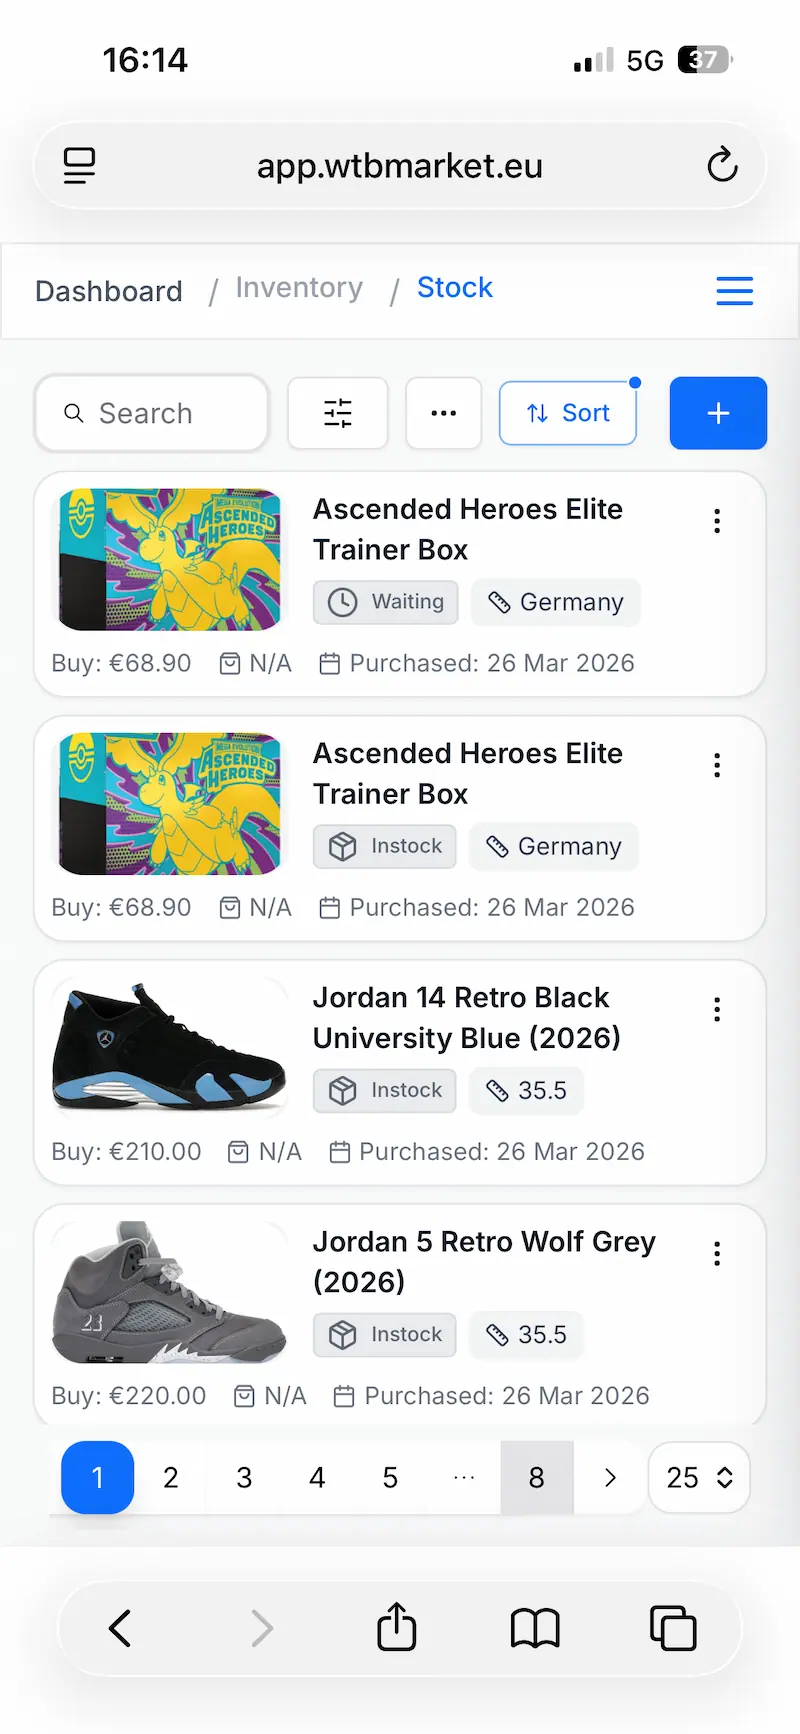
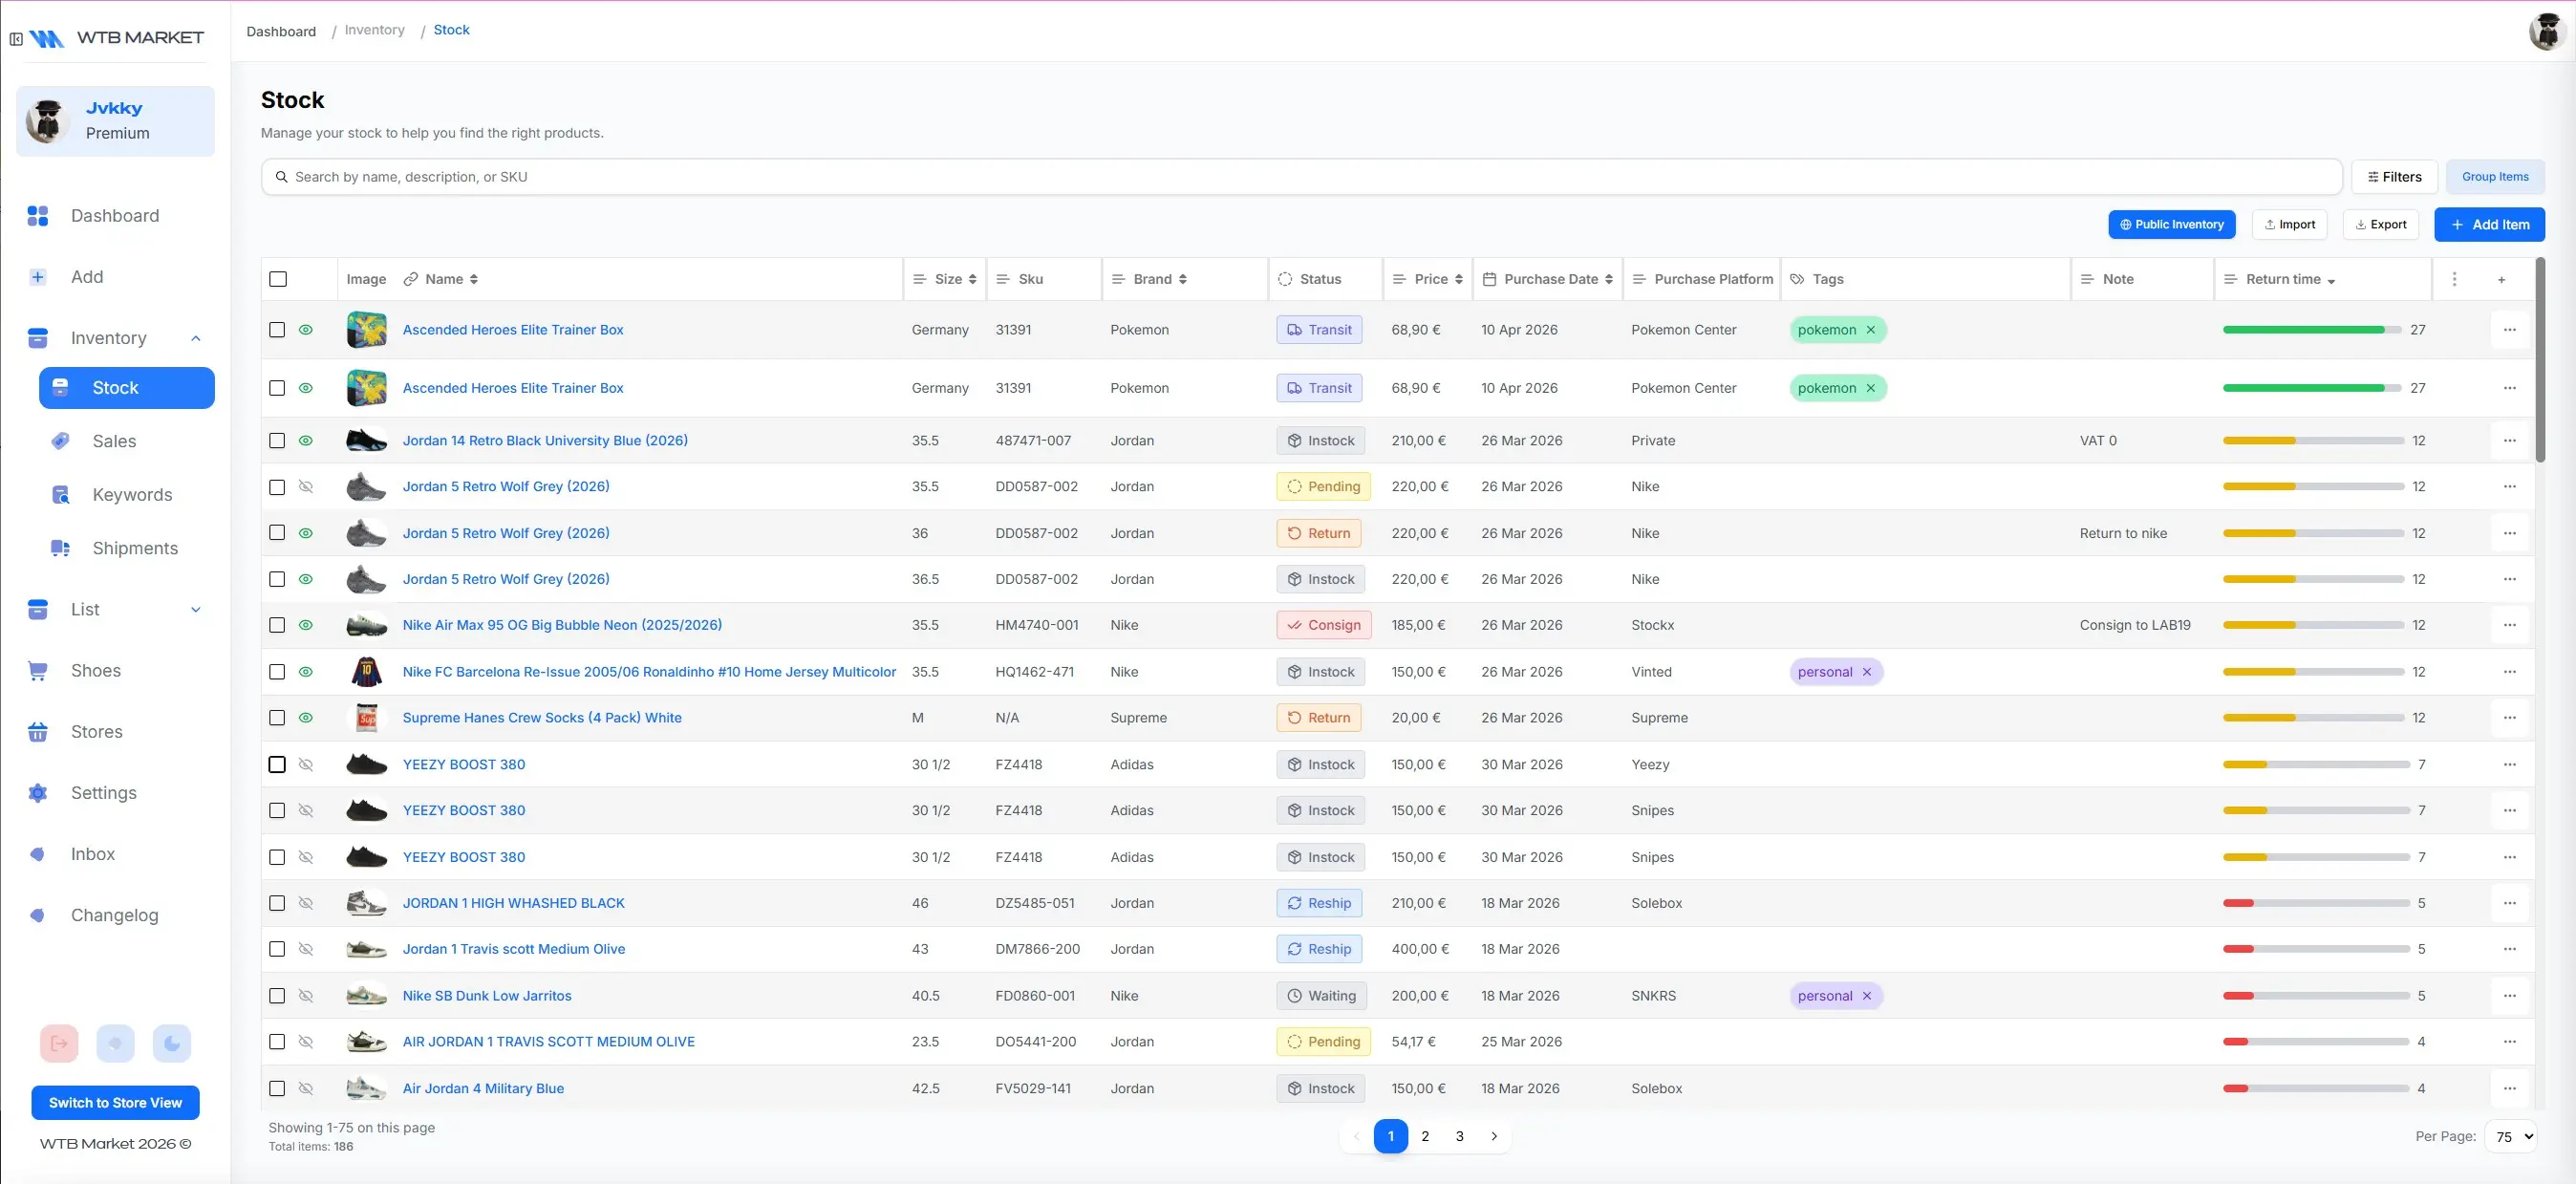
WTB Market is a reseller community born in 2022 on Discord. Before the platform, resellers were managing inventory in spreadsheets or manually despite existing tools. I decided to build a platform tailored to their needs, letting them manage their inventory, sales and daily operations, which quickly evolved into a full ecosystem.
I own the full technical stack while the community is operated by a business partner.
Highlights
Architecture
WTB Market is not a single app: it's a set of interconnected products.
Core platform | Inventory tracking | Analytics | CSV import | Storefront management.
Public want-to-buy lists for users and storefronts | API access via REST endpoints.
Notification layer | Guild roles | Real time notifications via webhooks or DMs.
Marketing channel | External leads contact form | Submissions shared on Discord.
Native mobile companion for on-the-go inventory management.
Key Challenges
Discord notifications
Backend Matching thousands of freeform WTB posts against user keywords in near-real-time without hitting Discord rate limits.
Discord notifications
Each message is normalized before matching (punctuation, regional suffixes, special characters stripped), then split into rows and tokenized. Matching fans out with p-limit (10 parallel workers) inside a serialized PQueue, matching one message at a time while processing ten users in parallel. Notifications go through a Bottleneck rate limiter at 40 req/s.
- ·Unknown guild members are migrated to an archive collection.
- ·Zero-match senders receive a DM with formatting tips.
- ·Webhook failures fall back to a direct DM.
- ·All ping events are persisted to a log collection for audit.
Multi-tier product lookup
Backend Ensuring reliable product search results even when external APIs fail or return incomplete data.
Multi-tier product lookup
External APIs often return incomplete or inconsistent data. I handle lookups through a fallback chain: provider API → MongoDB cache → provider slug lookup. The result is saved in the cache to prevent repeated misses.
- ·Items without a retail price are defaulted to 0 rather than null to keep the response shape consistent.
- ·Identifier is sanitized before all comparisons to avoid mismatches from scraped data.
- ·Cache auto-population is logged with the query string so new items added at runtime are auditable.
Deduplication at scale
Backend Aggregating 4,300+ items across stores and user lists into a single unified view without quadratic growth in lookup latency.
Deduplication at scale
Stores and user lists are fetched in parallel, then merged in a single pass using a Map keyed by normalized slugs. This replaced a previous Array.find loop that scanned ~6.9M entries at 4300 items.
- ·Sizes are normalized before the merge.
- ·Freemium restrictions are enforced at the data layer, not on the client.
- ·The count field reflects total sources (stores + lists) so sorting stays consistent.
Reversible mutations
Frontend Supporting undo actions for every data operation without a dedicated undo stack.
Reversible mutations
Before each mutation, a reverse payload is created from the original data and time bounded. The undo action re-enters the same mutation pipeline, reusing the same validation, error handling and API normalization.
- ·Undo is blocked if the user has hit their quota limit between the original action and the reversal attempt.
- ·If the undo fails, a new second error toast surfaces without replacing or dismissing the original.
- ·Bulk operations generate individual reverse payloads per row, so partial undos remain possible.
What I'd Do Differently
Standardize environments earlier
Early deployments were messy: too many branches and ad-hoc deployments led to config problems and confusion. Dev, beta and production improved stability and consistency. I'd set up this flow from the start.
Define data before the schema
MongoDB's flexibility worked well when I started, but as time passed, aggregations and multi-field filters became harder to manage. I'd define a clearer data model upfront, considering a relational approach where it fits instead of pushing everything into the document model.
Normalize the keyword store
Matching all users' keywords means iterating the entire collection (~7 million operations per message). I'd normalize the keyword store with proper indexing and enforce structured input: users pick from known SKUs on the dashboard instead of typing freeform text, making matches fast and exact.
Evolution
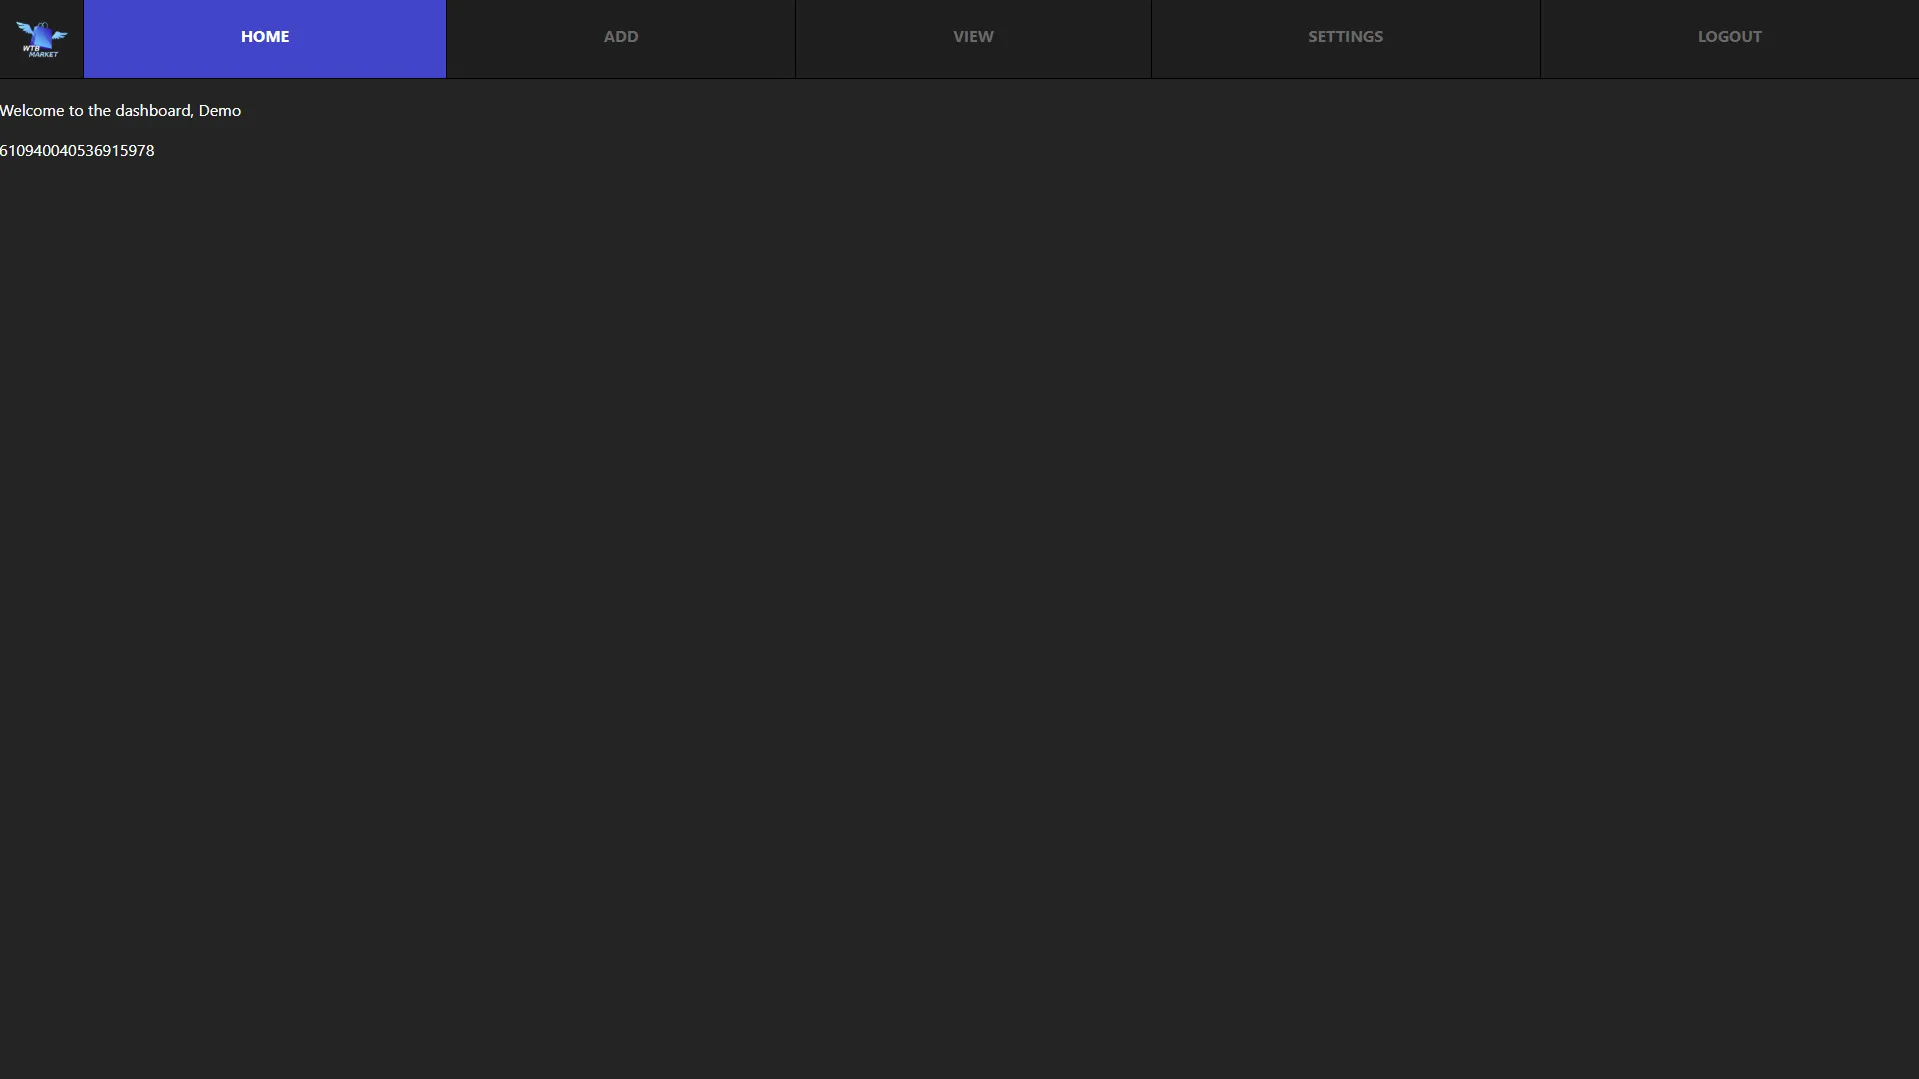
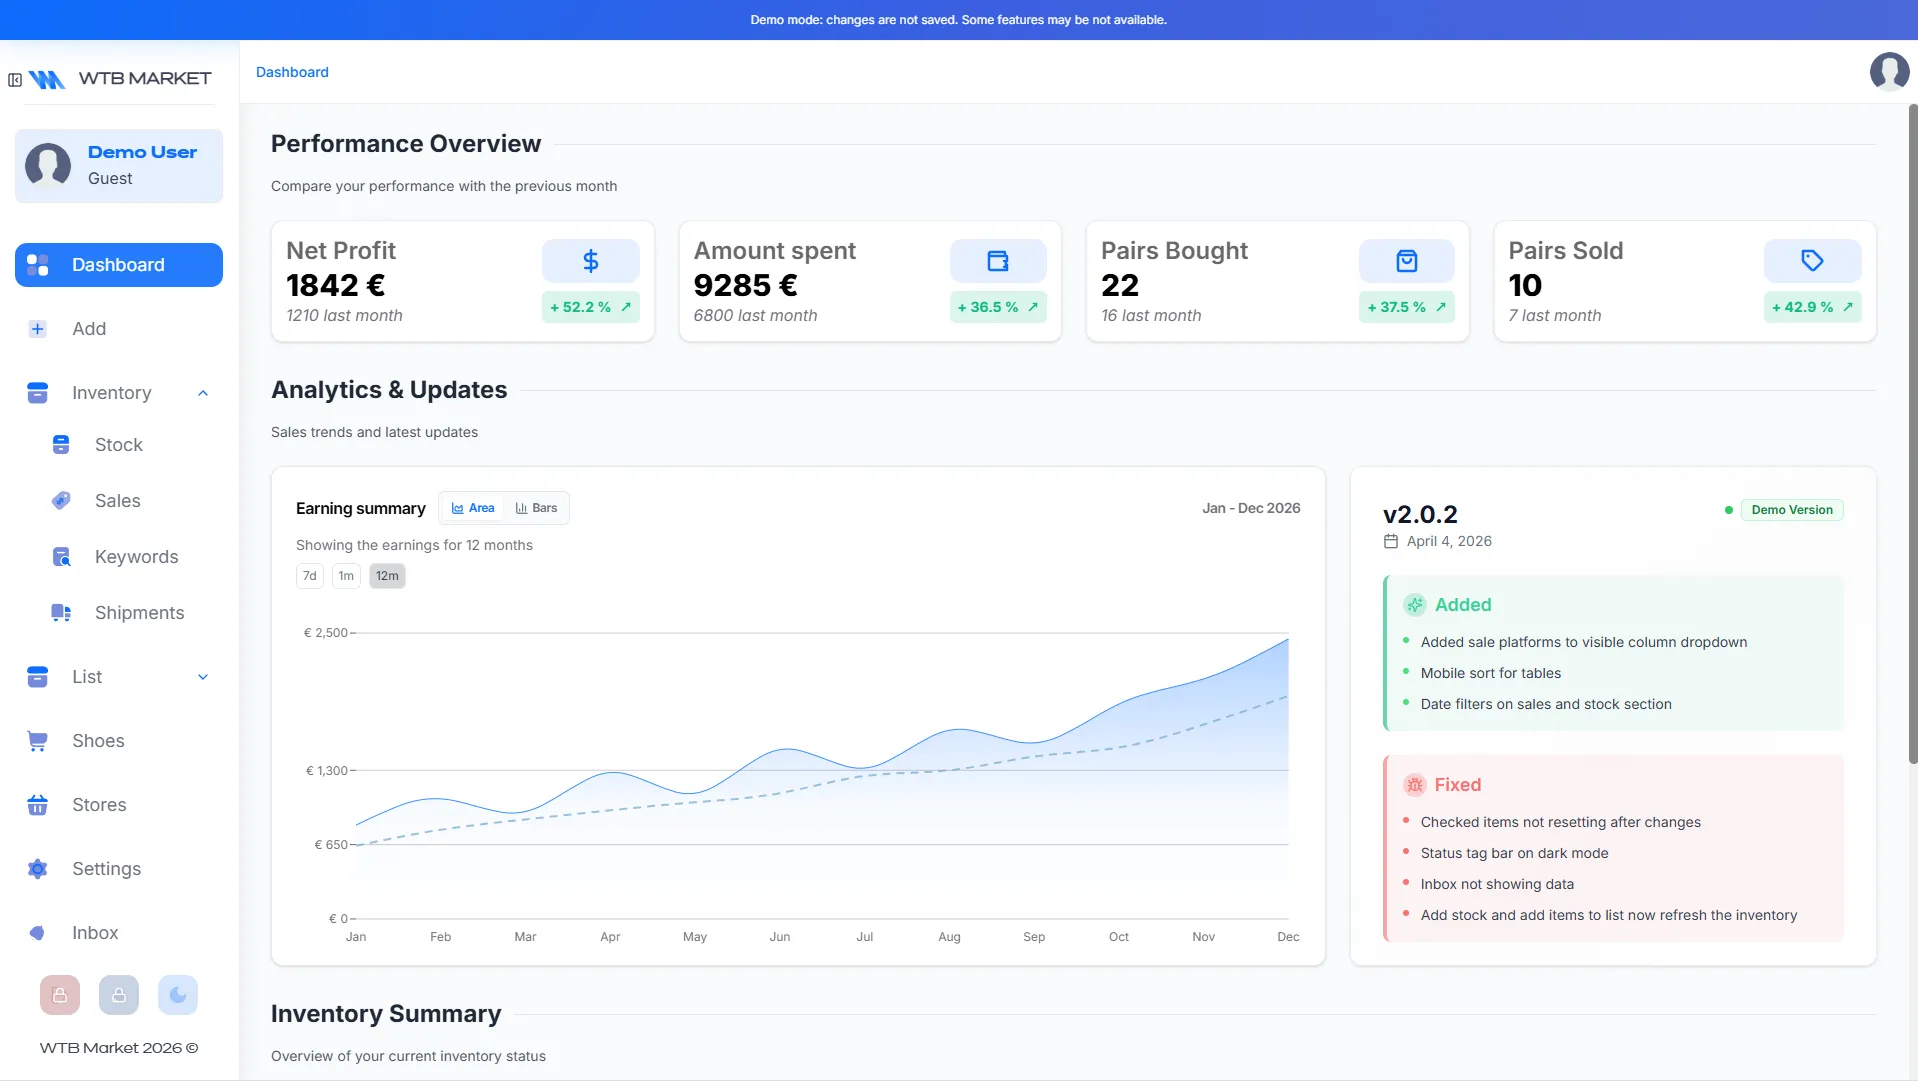
Drag the handle to compare the 2023 build with the current one.
 2023 Today
Complete Stack


Next case study
Atlas
Personal finance dashboard
Need something like this?
I build custom internal tools and automation systems around real business workflows, from pricing pipelines to inventory dashboards. I'm not taking new client work at the moment, but I'm happy to hear about what's next.
Get in touch